WeMM-Embedding: WeChat Multi-Modal Embedding
English | 中文

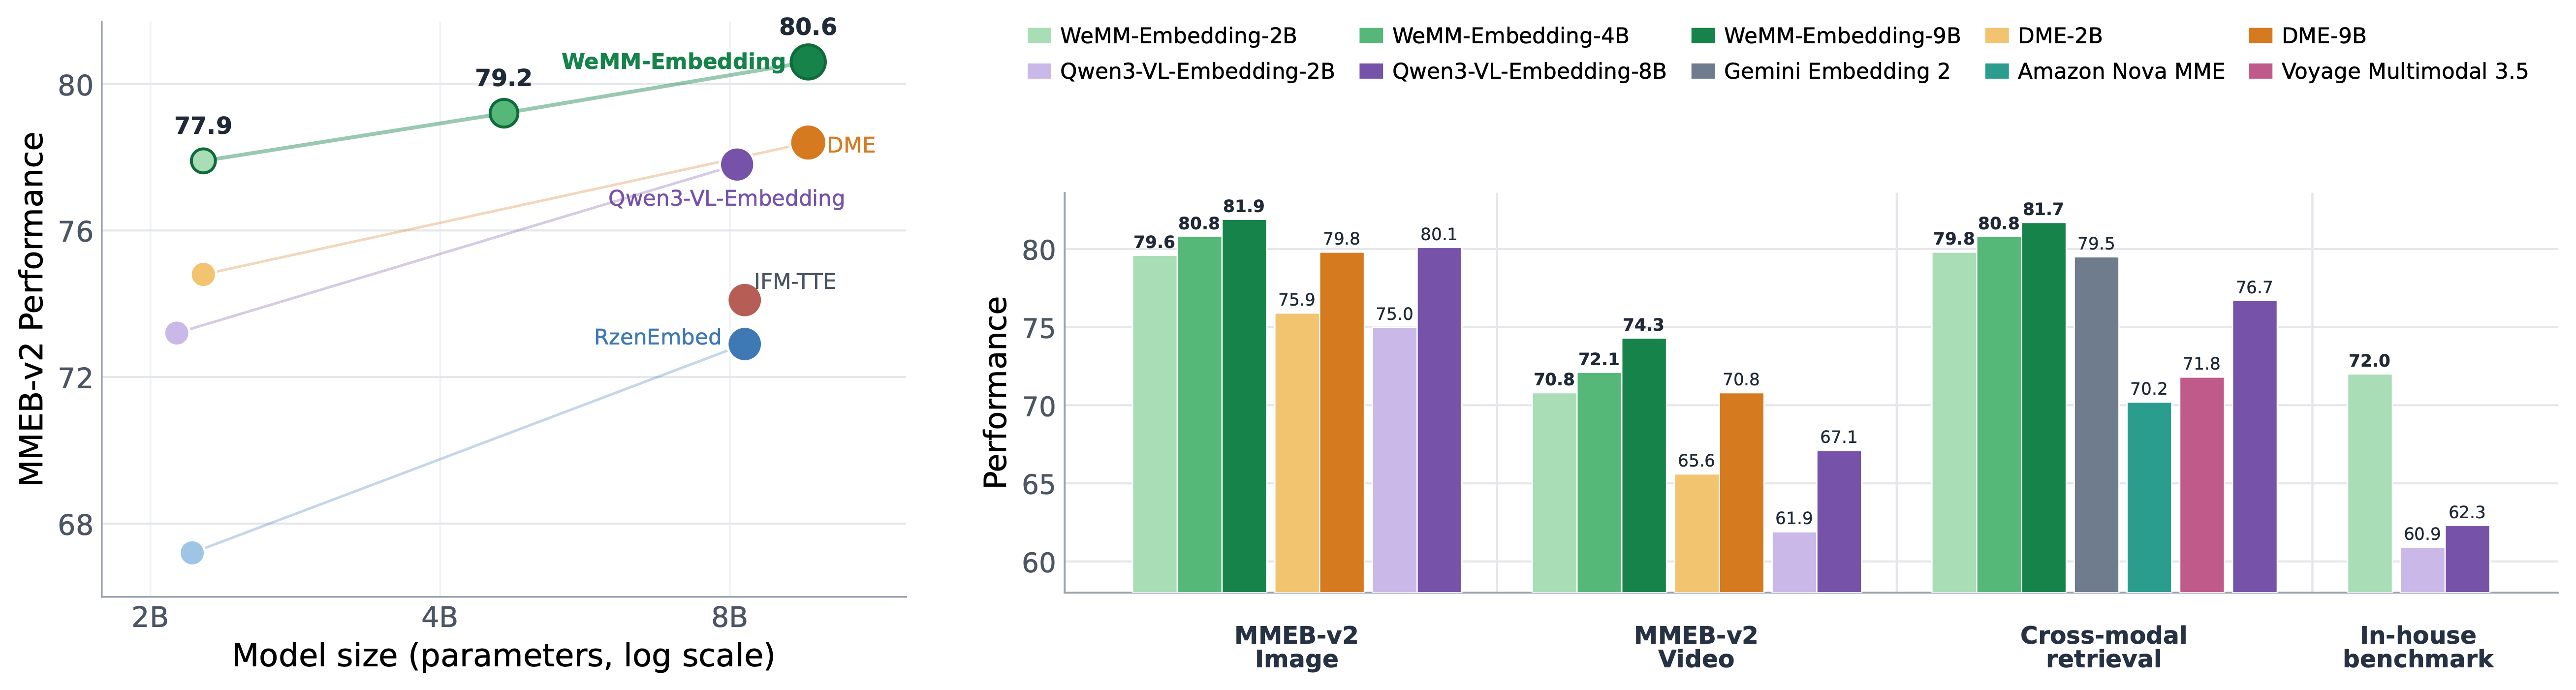
WeMM-Embedding is a family of universal multimodal embedding models developed by the WeChat Vision team. It provides unified representations for text, images, videos, visual documents, and interleaved multimodal inputs, achieving state-of-the-art performance across multiple benchmarks covering diverse tasks and domains.
Model Zoo
| Model | Matryoshka dimensions | Hugging Face |
|---|---|---|
| WeMM-Embedding-2B | 64, 128, 256, 512, 1024, 2048 |
🤗 Link |
| WeMM-Embedding-4B | 64, 128, 256, 512, 1024, 2560 |
🤗 Link |
| WeMM-Embedding-9B | 64, 128, 256, 512, 1024, 2048, 4096 |
🤗 Link |
All models support text, images, videos, visual documents, and interleaved multimodal inputs. Embeddings are obtained from the last-layer hidden state at the dedicated <embedding> token position, followed by L2 normalization. Audio input is not currently supported.
Installation
pip install -r requirements.txt
Transformers
We recommend using transformers==5.2.0 for inference and reproducibility, as newer versions may differ in preprocessing behavior.
python examples/transformers_inference.py \
  --model /path/to/WeMM-Embedding-2B \
  --image /path/to/image.jpg \
  --video /path/to/video.mp4 \
  --dimension 2048
The example produces independent text, image, and video embeddings. Omit --dimension for the full embedding dimension.
Sentence Transformers
python examples/sentence_transformers_inference.py \
  --model /path/to/WeMM-Embedding-2B \
  --image /path/to/image.jpg \
  --video /path/to/video.mp4 \
  --dimension 2048
SentenceTransformer loads the model directly, so a Hugging Face model id such as tencent/WeMM-Embedding-2B also works in place of a local path. Text, image, and video inputs go through SentenceTransformer.encode(), and MRL is selected with --dimension.
Serving
Tested versions: vLLM 0.27.0 and SGLang 0.5.9.
vLLM:
MODEL_PATH=/path/to/WeMM-Embedding-2B
vllm serve "$MODEL_PATH" \
  --runner pooling \
  --chat-template "$MODEL_PATH/embedding_chat_template.jinja"
SGLang:
MODEL_PATH=/path/to/WeMM-Embedding-2B
python scripts/patch_sglang_video.py
python -m sglang.launch_server \
  --model-path "$MODEL_PATH" \
  --is-embedding \
  --enable-precise-embedding-interpolation
Equivalent one-command wrappers are available in scripts/serve_vllm.sh and scripts/serve_sglang.sh.
Matryoshka Embeddings
For a supported dimension d, truncate the full embedding and normalize it again:
embedding = torch.nn.functional.normalize(embedding[..., :d], dim=-1)
On MMEB-v2, the 2B model at 256 dimensions retains 98.7% of its full-dimensional image and video performance.
Evaluation
MMEB-v2
Results on 78 datasets from Table 1 of the technical report. Image and video tasks use Hit@1, while visual-document tasks use NDCG@5. Higher is better.
| Model | Size | AVG | Image | Video | VisDoc |
|---|---|---|---|---|---|
| VLM2Vec | 2B | 4 |