Datalab
State of the Art models for Document Intelligence


lift
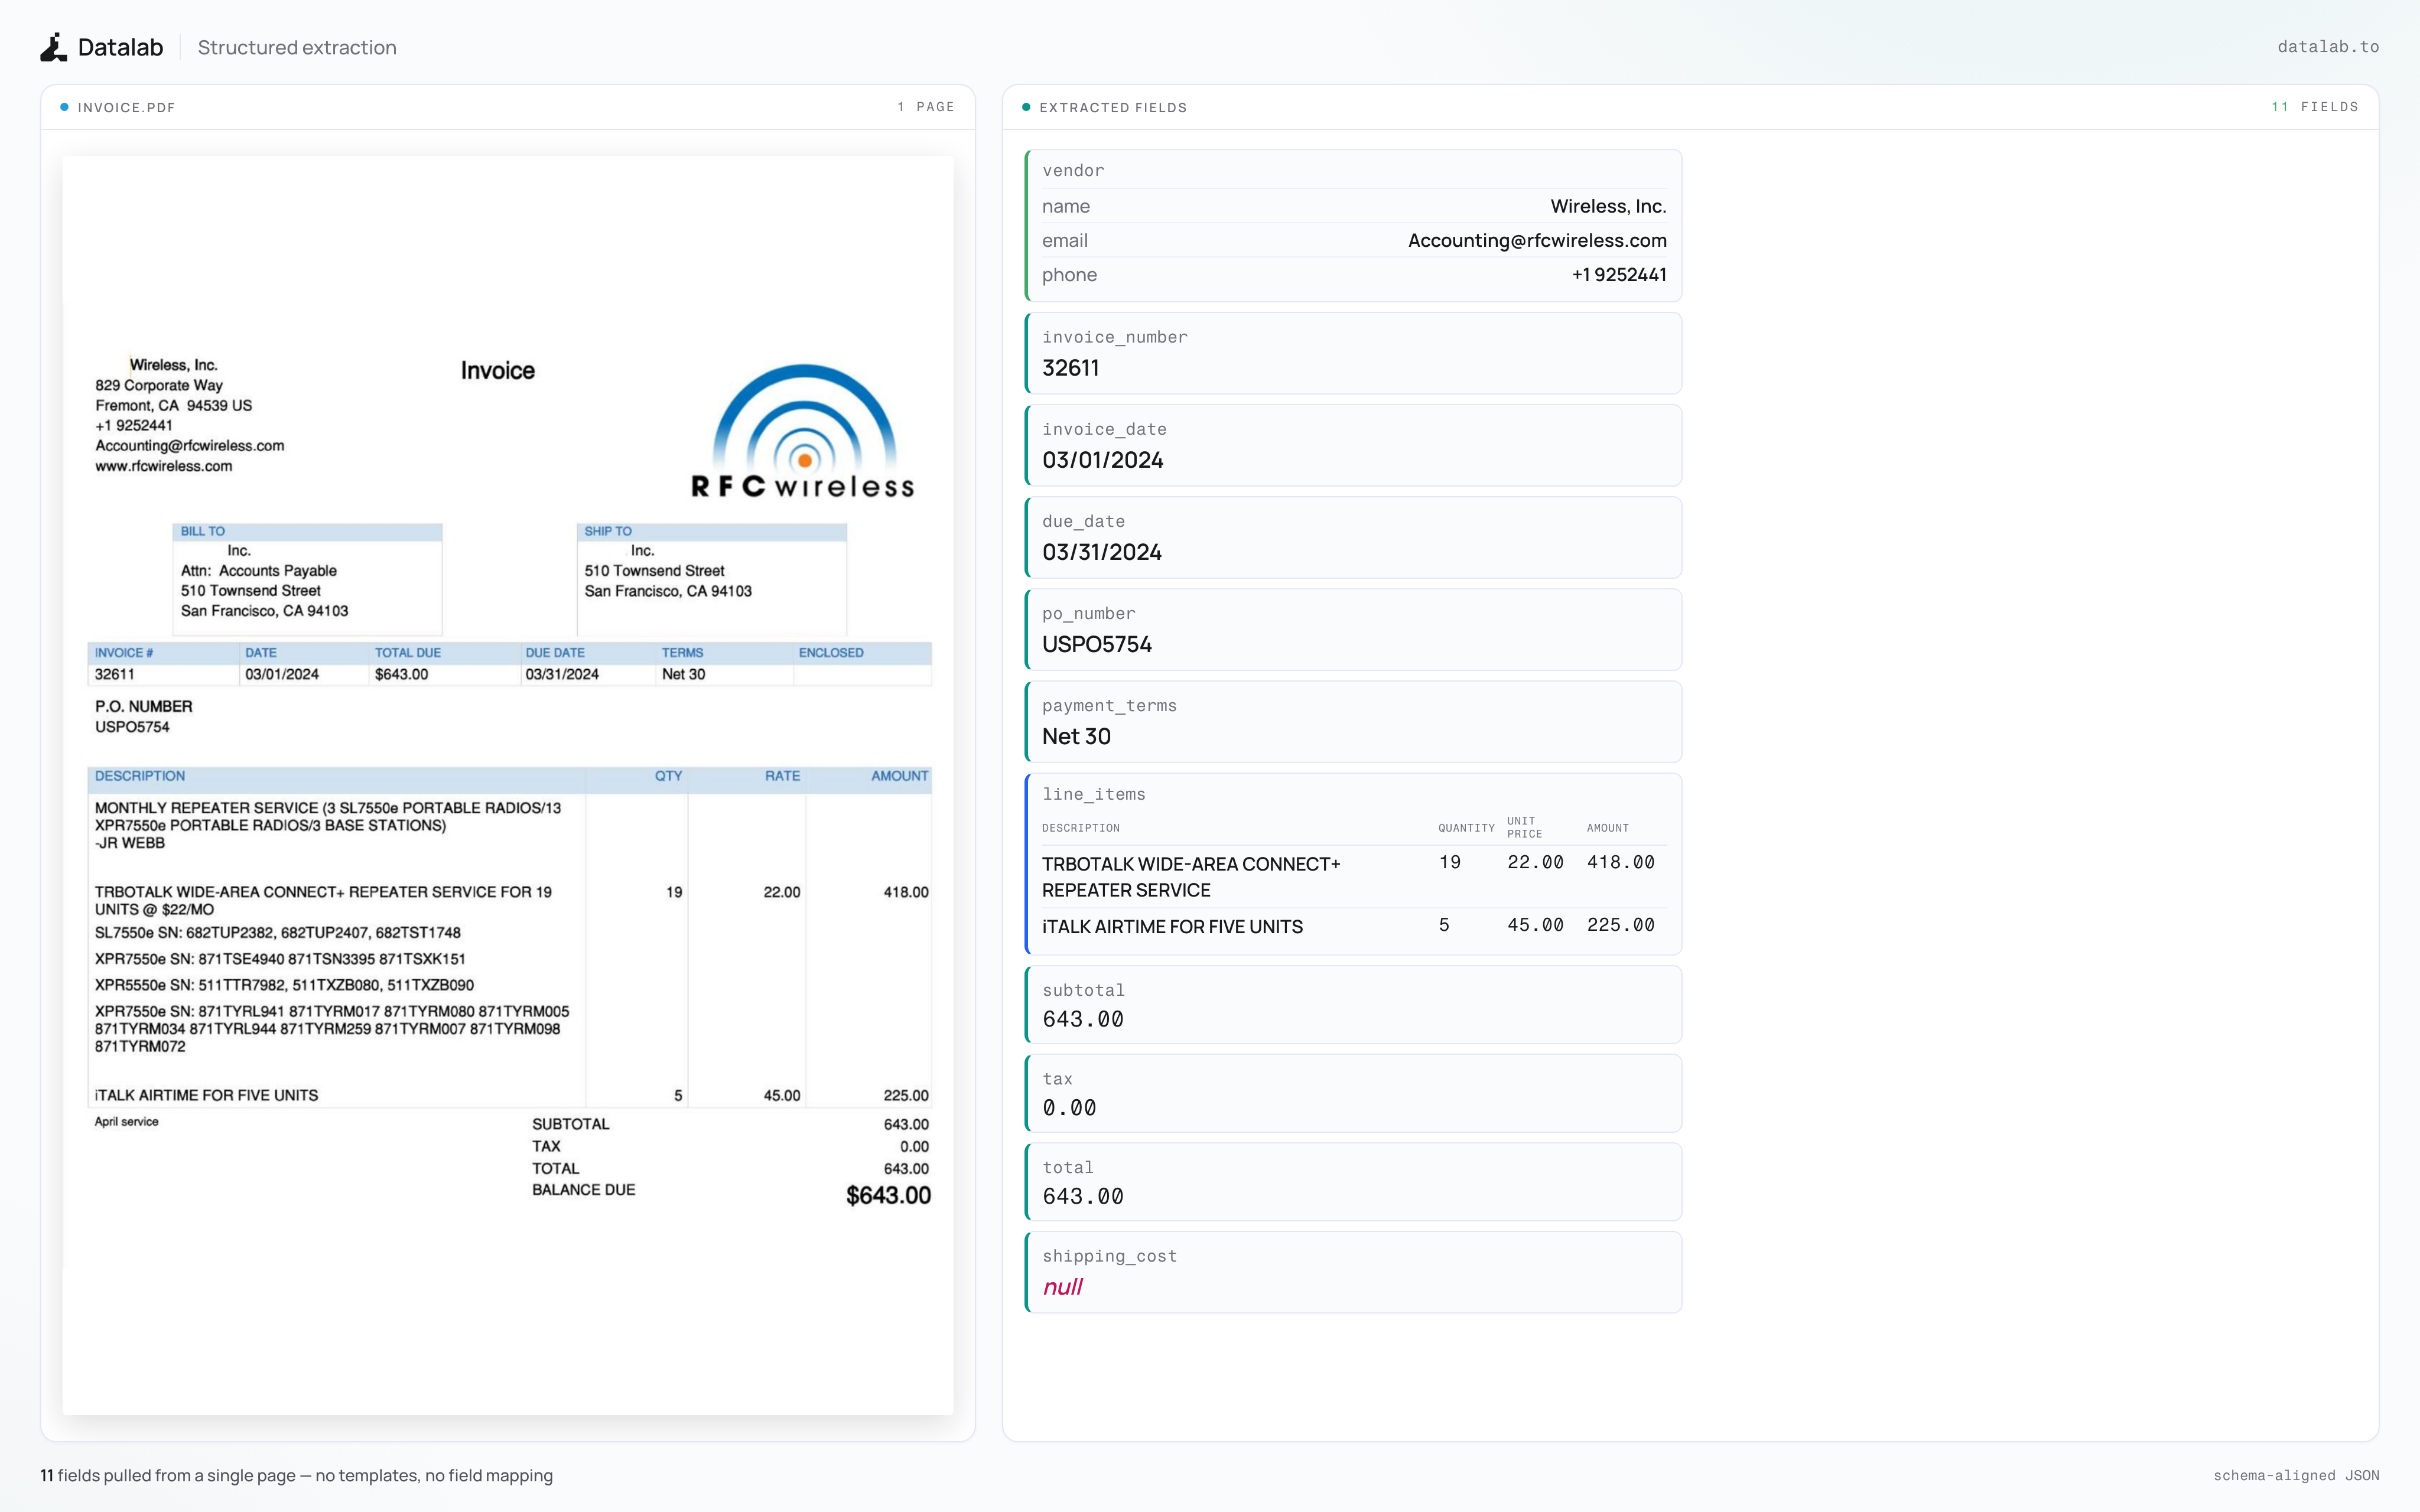
lift extracts structured JSON from PDFs and images by passing a schema. It's a 9B vision model that returns a JSON object matching your schema, with schema-constrained decoding guaranteeing valid output.
Try lift on Datalab
Our managed platform runs improved extraction with higher accuracy than the open weights, plus per-field verification, citations, and confidence scores.
If you have high volume workloads, we offer a batch processing service that has processed 1B+ pages per week.
Get started with $20 in free credits per month — sign up - takes under 30 seconds - or try lift in our public playground.
Commercial self-hosting requires a license — see Commercial usage. For on-prem licensing, contact us.
Features
- Extract structured data from documents
- Pass any JSON schema
- Handles multi-page documents in a single pass, including values that span pages
- Two inference modes: local (HuggingFace) and remote (vLLM server)
- CLI for single files, inline schemas, or whole directories
- Schema Studio: a Streamlit app to build, save, and test schemas against your documents
Quickstart
The easiest way to start is with the CLI tools:
pip install lift-pdf

# With vLLM (recommended, lightweight install)
lift_vllm
lift_extract input.pdf ./output --schema schema.json

# With HuggingFace (requires torch)
pip install lift-pdf[hf]
lift_extract input.pdf ./output --schema schema.json --method hf
Benchmarks
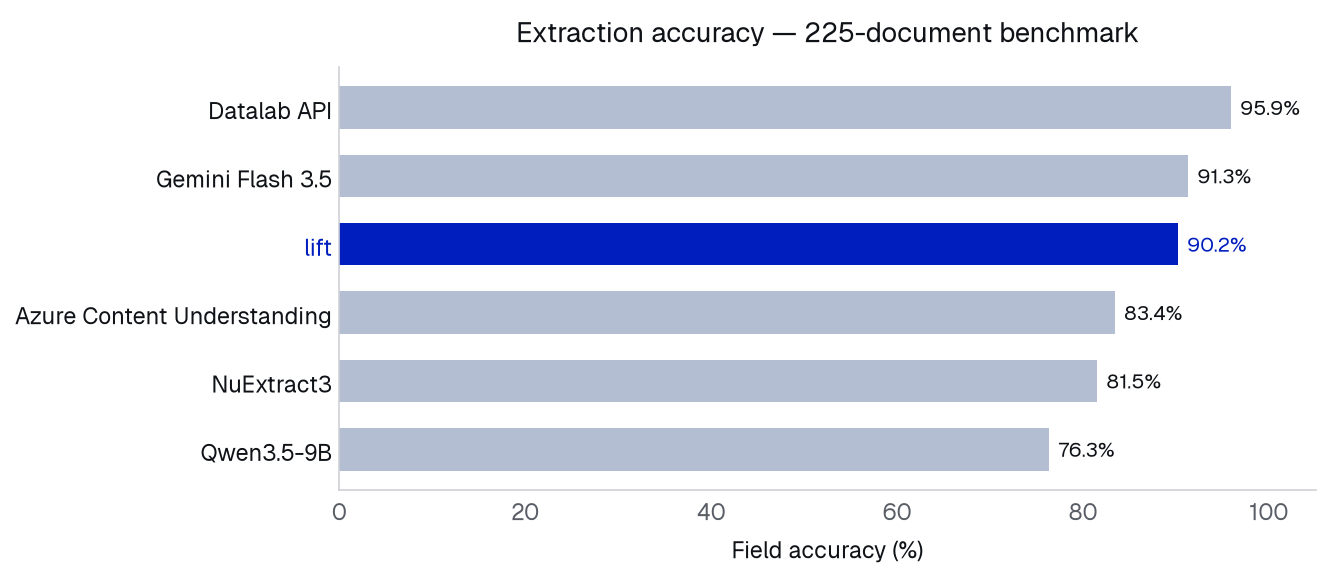
Evaluated on a 225-document extraction benchmark (6–64 pages per document, ~11,000 scored fields) with adversarial cases planted throughout: cross-page values, exhaustive lists, fields that must be left null, near-miss distractors, multi-source aggregation. Scoring is deterministic exact-match against ground truth (numeric tolerance, normalized strings).
All models receive the same rendered page images, and extract each document in a single pass.
| Model | Size | Field accuracy | Full-document accuracy | Median latency* | Features |
|---|---|---|---|---|---|
| Datalab API | — | 95.9% | 44.4% | 30.8s | Citations + Verification |
| Gemini Flash 3.5 | — | 91.3% | 40.0% | 28.1s | |
| lift | 9B | 90.2% | 20.9% | 9.5s | |
| Azure Content Understanding |