README.md2 min read
LLM Wiki
A personal knowledge base that builds itself.
LLM reads your documents, builds a structured wiki, and keeps it current.
What is this? • Features • Tech Stack • Installation • Credits • License
Features
- Two-Step Chain-of-Thought Ingest — LLM analyzes first, then generates wiki pages with source traceability and incremental cache
- Multimodal Image Ingestion — extract embedded images from PDFs, generate factual captions with a vision LLM, surface them in image-aware search results with lightbox preview and jump-to-source
- Multi-format Document Parsing — ingest PDF, Office documents, EPUB/MOBI, Org mode, images, media, web clips, and batches of URLs, with built-in, cloud, or local MinerU PDF processing
- Flexible Model Configuration — configure models per project, route Chat and Ingest independently, and manage custom providers, headers, and streaming output
- Source-grounded Retrieval — use Read Sources Only mode to answer exclusively from original imported material
- Project Management & Migration — export and import complete project archives across devices, and rebuild the Wiki index from existing pages
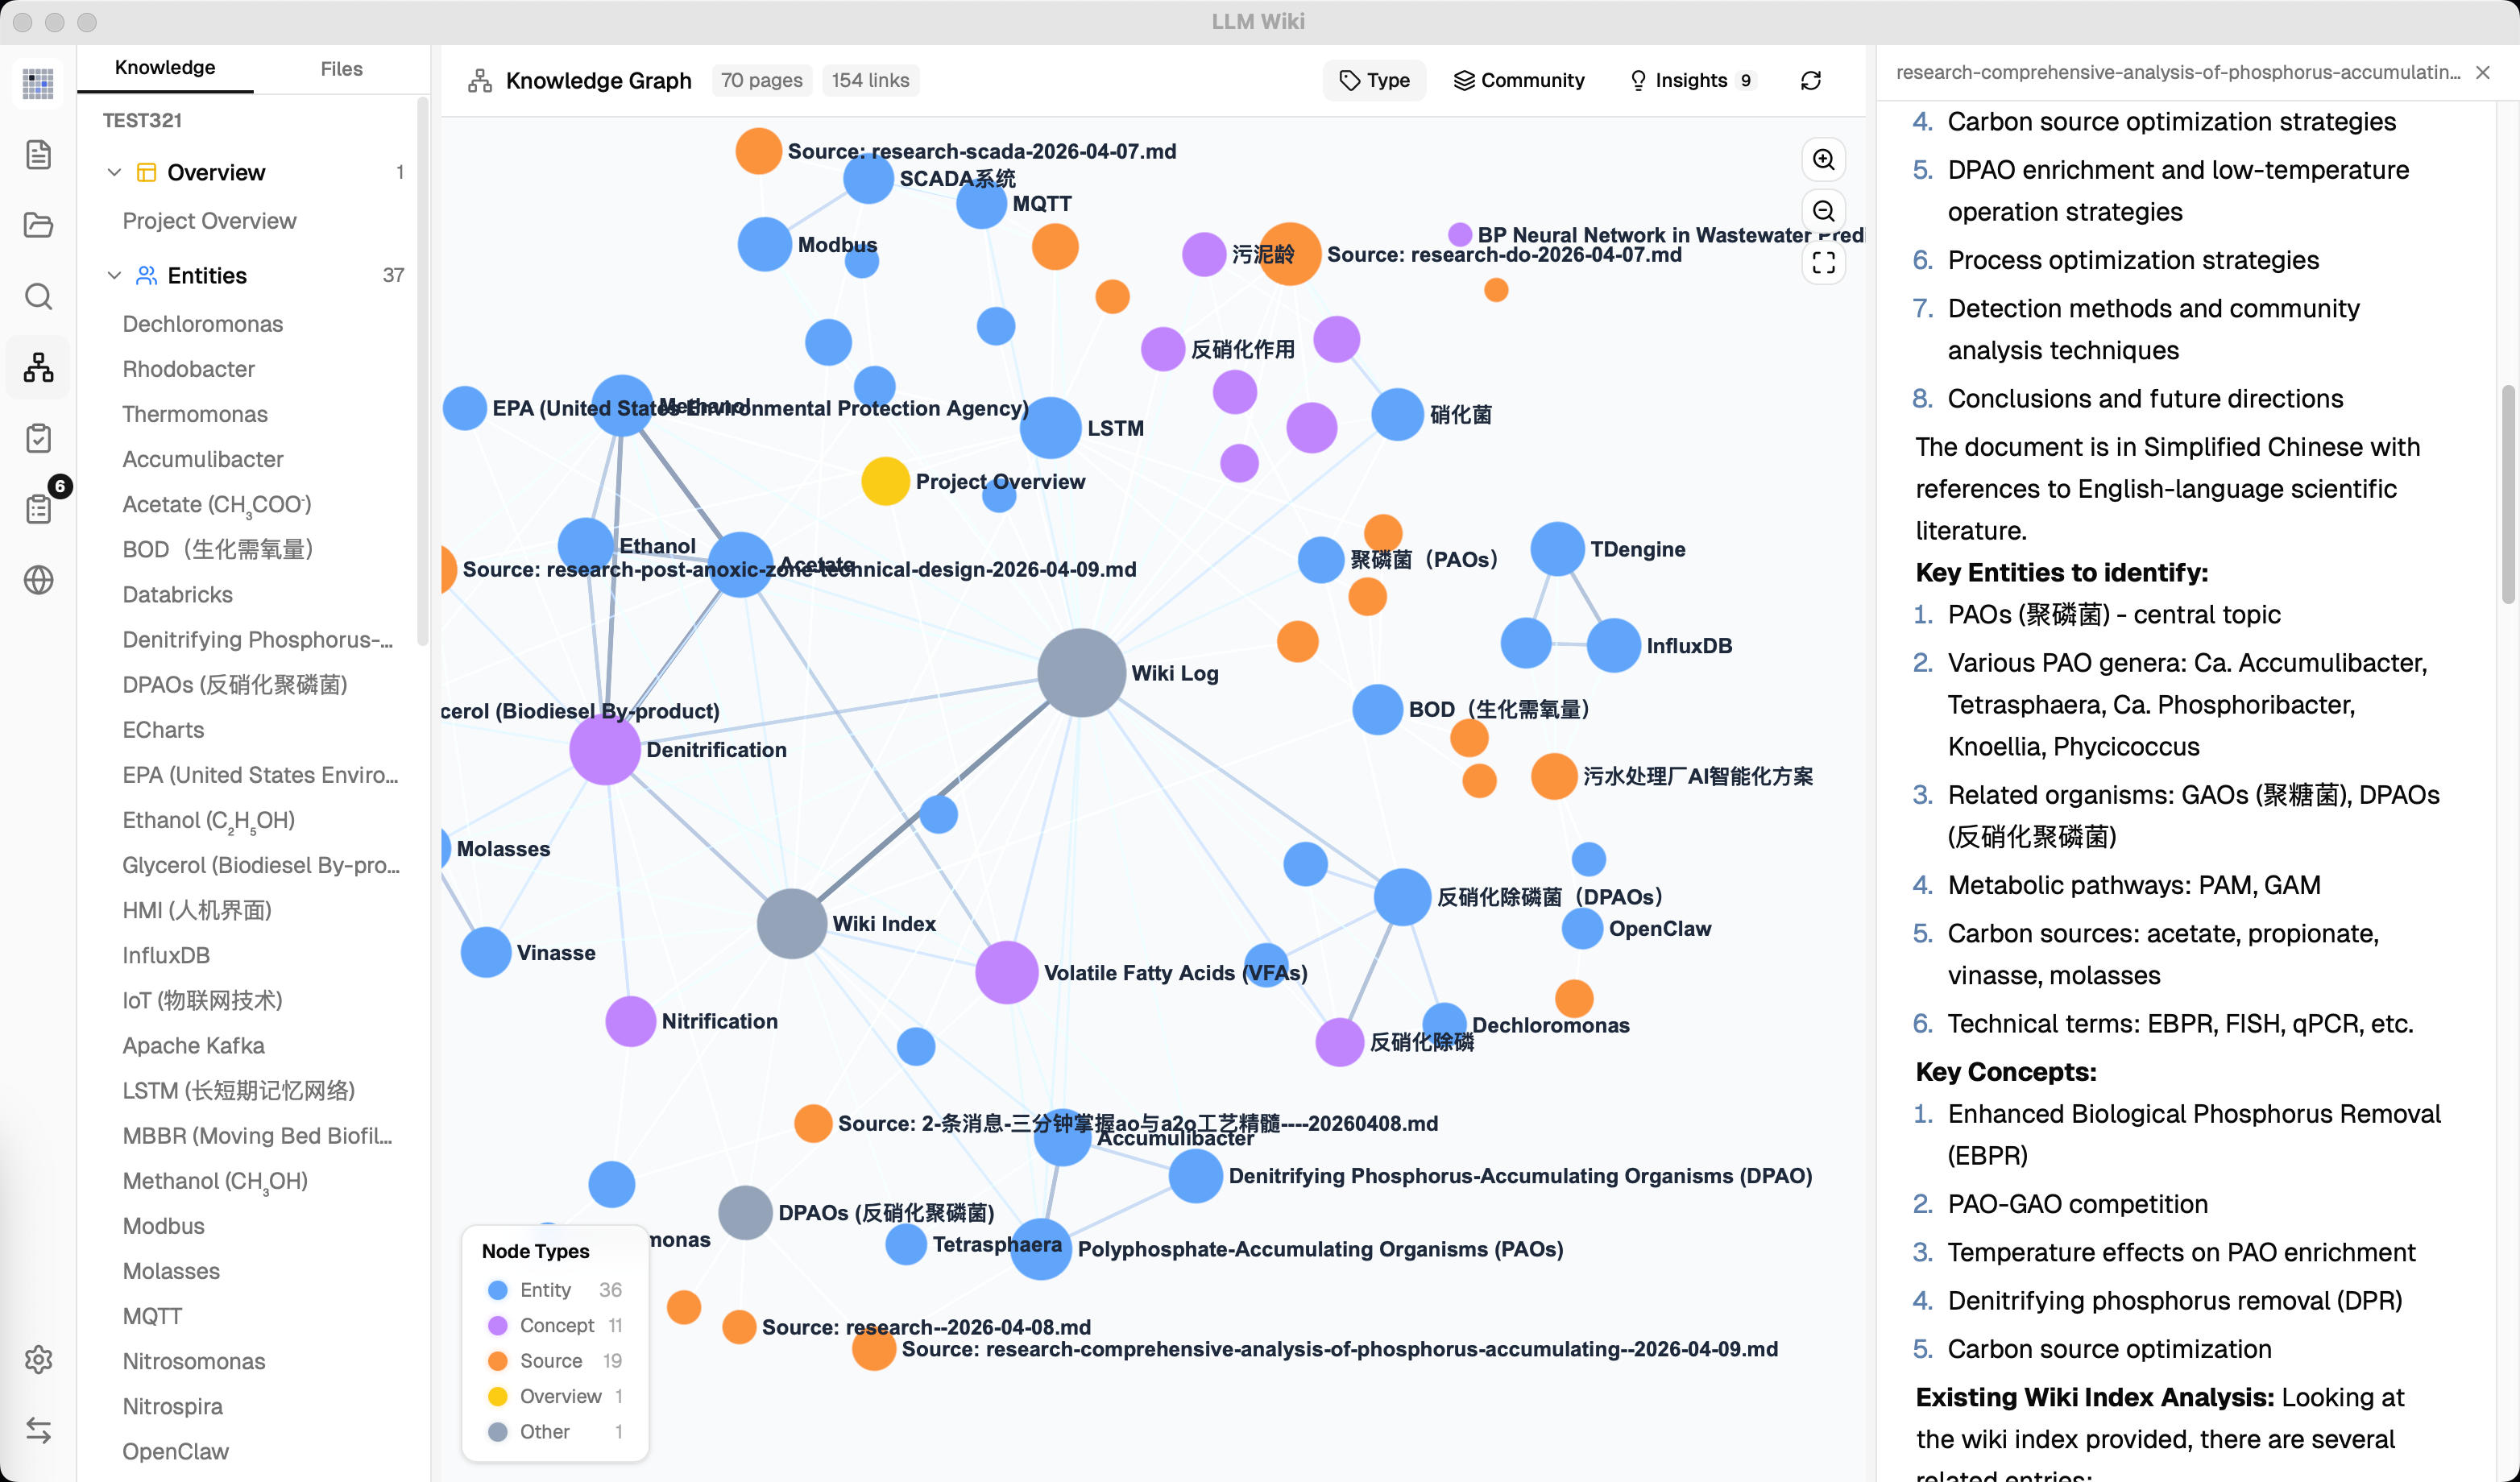
- 4-Signal Knowledge Graph — relevance model with direct links, source overlap, Adamic-Adar, and type affinity
- Louvain Community Detection — automatic knowledge cluster discovery with cohesion scoring
- Graph Insights — surprising connections and knowledge gaps with one-click Deep Research
- Vector Semantic Search — optional embedding-based retrieval via LanceDB, supports any OpenAI-compatible endpoint
- Persistent Ingest Queue — serial processing with crash recovery, cancel, retry, and progress visualization
- Folder Import — recursive folder import preserving directory structure, folder context as LLM classification hint
- Source Folder Auto-Watch — detects external changes in
raw/sources/and keeps ingest/delete cleanup in sync - Deep Research — LLM-optimized search topics, multi-query web search via Tavily, SerpApi, or SearXNG, auto-ingest results into wiki
- Rust Backend Chat Agent — tool-using chat runtime with wiki/source/graph/web retrieval, workspace file generation, shell approval, cancellation, and streaming tool events
- Agent Skills — scan and enable local
SKILL.mdfolders, select skills with/skill, and let the Agent read skill instructions on demand - Generated Outputs Preview — Agent-created Markdown, HTML, images, and other workspace files appear as outputs with preview and quick folder access
- Mermaid Diagram Rendering — render Mermaid code blocks directly in chat and preview, with compact syntax-error cards instead of raw parser output
- Async Review System — LLM flags items for human judgment, predefined actions, pre-generated search queries
- Chrome Web Clipper — one-click web page capture with auto-ingest into knowledge base
- Local HTTP API + MCP Server + AI Agent Skill — built-in
127.0.0.1:19828JSON API and bundled MCP server for hybrid search, file read, graph traversal, and source rescan; ready-made agent skill installs into Claude Code / Codex with one command (npx skills add …)
What is this?
LLM Wiki is a cross-platform desktop application that turns your documents into an organized, interlinked knowledge base — automatically. Instead of traditional