kev
Jev-inspired decision model. Typed questions in, calibrated probabilities out, one forward pass.
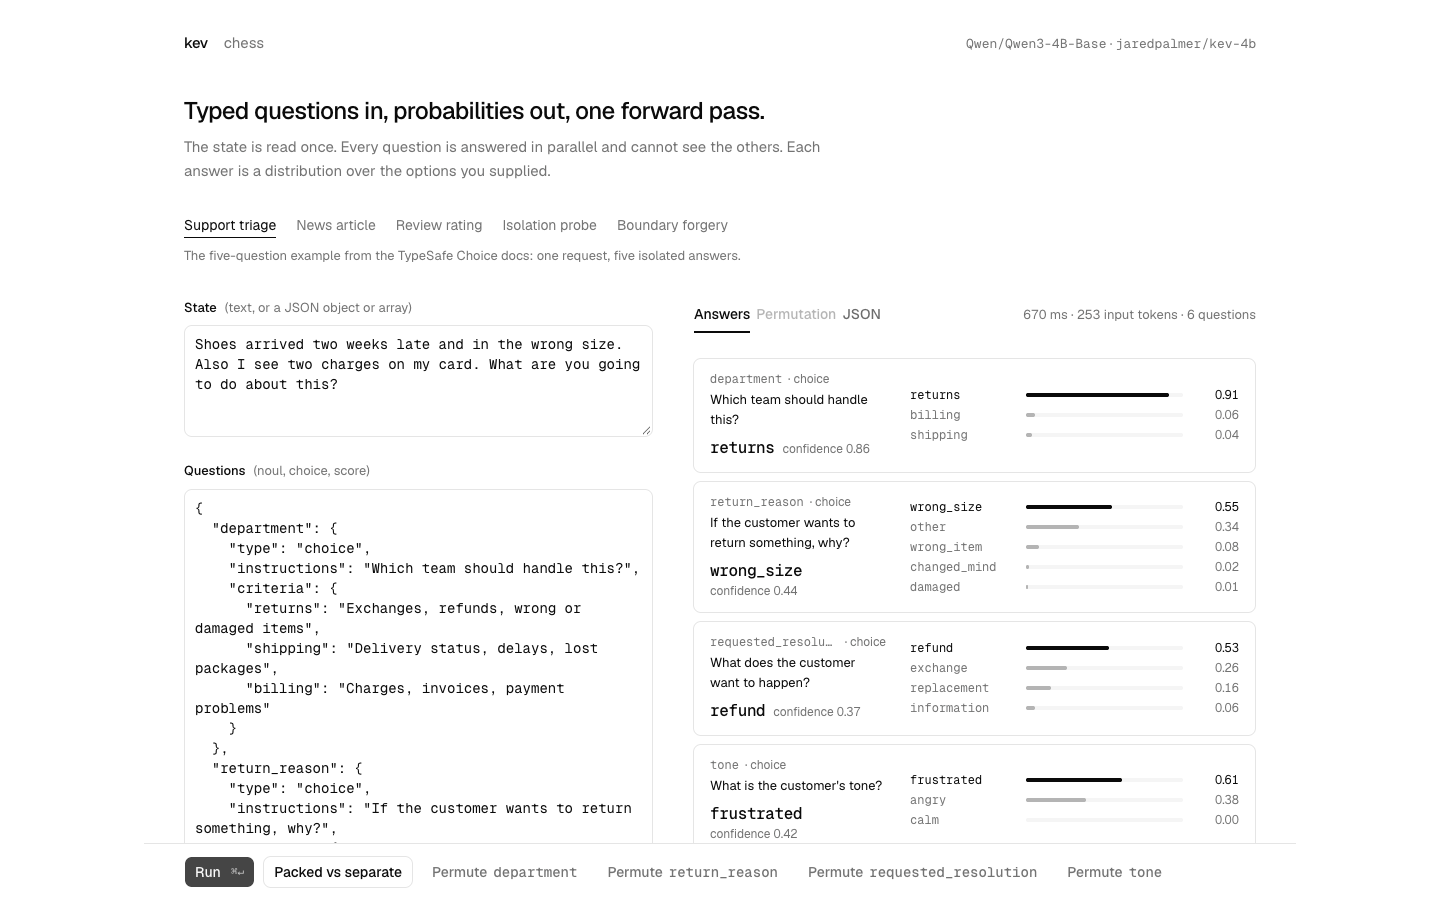
kev is a LoRA adapter and a small readout head on top of a Qwen base model (0.5B to 8B). It reads a document once and answers many typed questions about it in parallel, in a single prefill pass with no decoding. The document and every question are packed into one sequence; a block-causal mask lets each question see the document but never another question. A pointer head then scores each question's options against its decision token and applies softmax. Those probabilities are the output. The head is trained with cross-entropy against labelled outcomes, so the probabilities are learned rather than generated as text.
The architecture follows the reconstruction of TypeSafe's Jev in Jev's Architecture Unmasked. The API follows TypeSafe's System One contract, so the official typesafe-sdk works against a local kev server with a base_url change.
Highlights
- Three question types.
noul(yes/no),choice(2–255 options),score(ordered levels). One shared readout. - One pass, many answers. The state is encoded once. Questions run as isolated branches under a block-causal mask.
- Isolation is exact. A question cannot see a sibling question. Packed and separate requests agree to
4e-6. - Probabilities, not prose. Trained with cross-entropy on labelled outcomes. Out of domain,
kev-8bhas Brier 0.34 and 8% confident errors on sources it never saw. - Drop-in API.
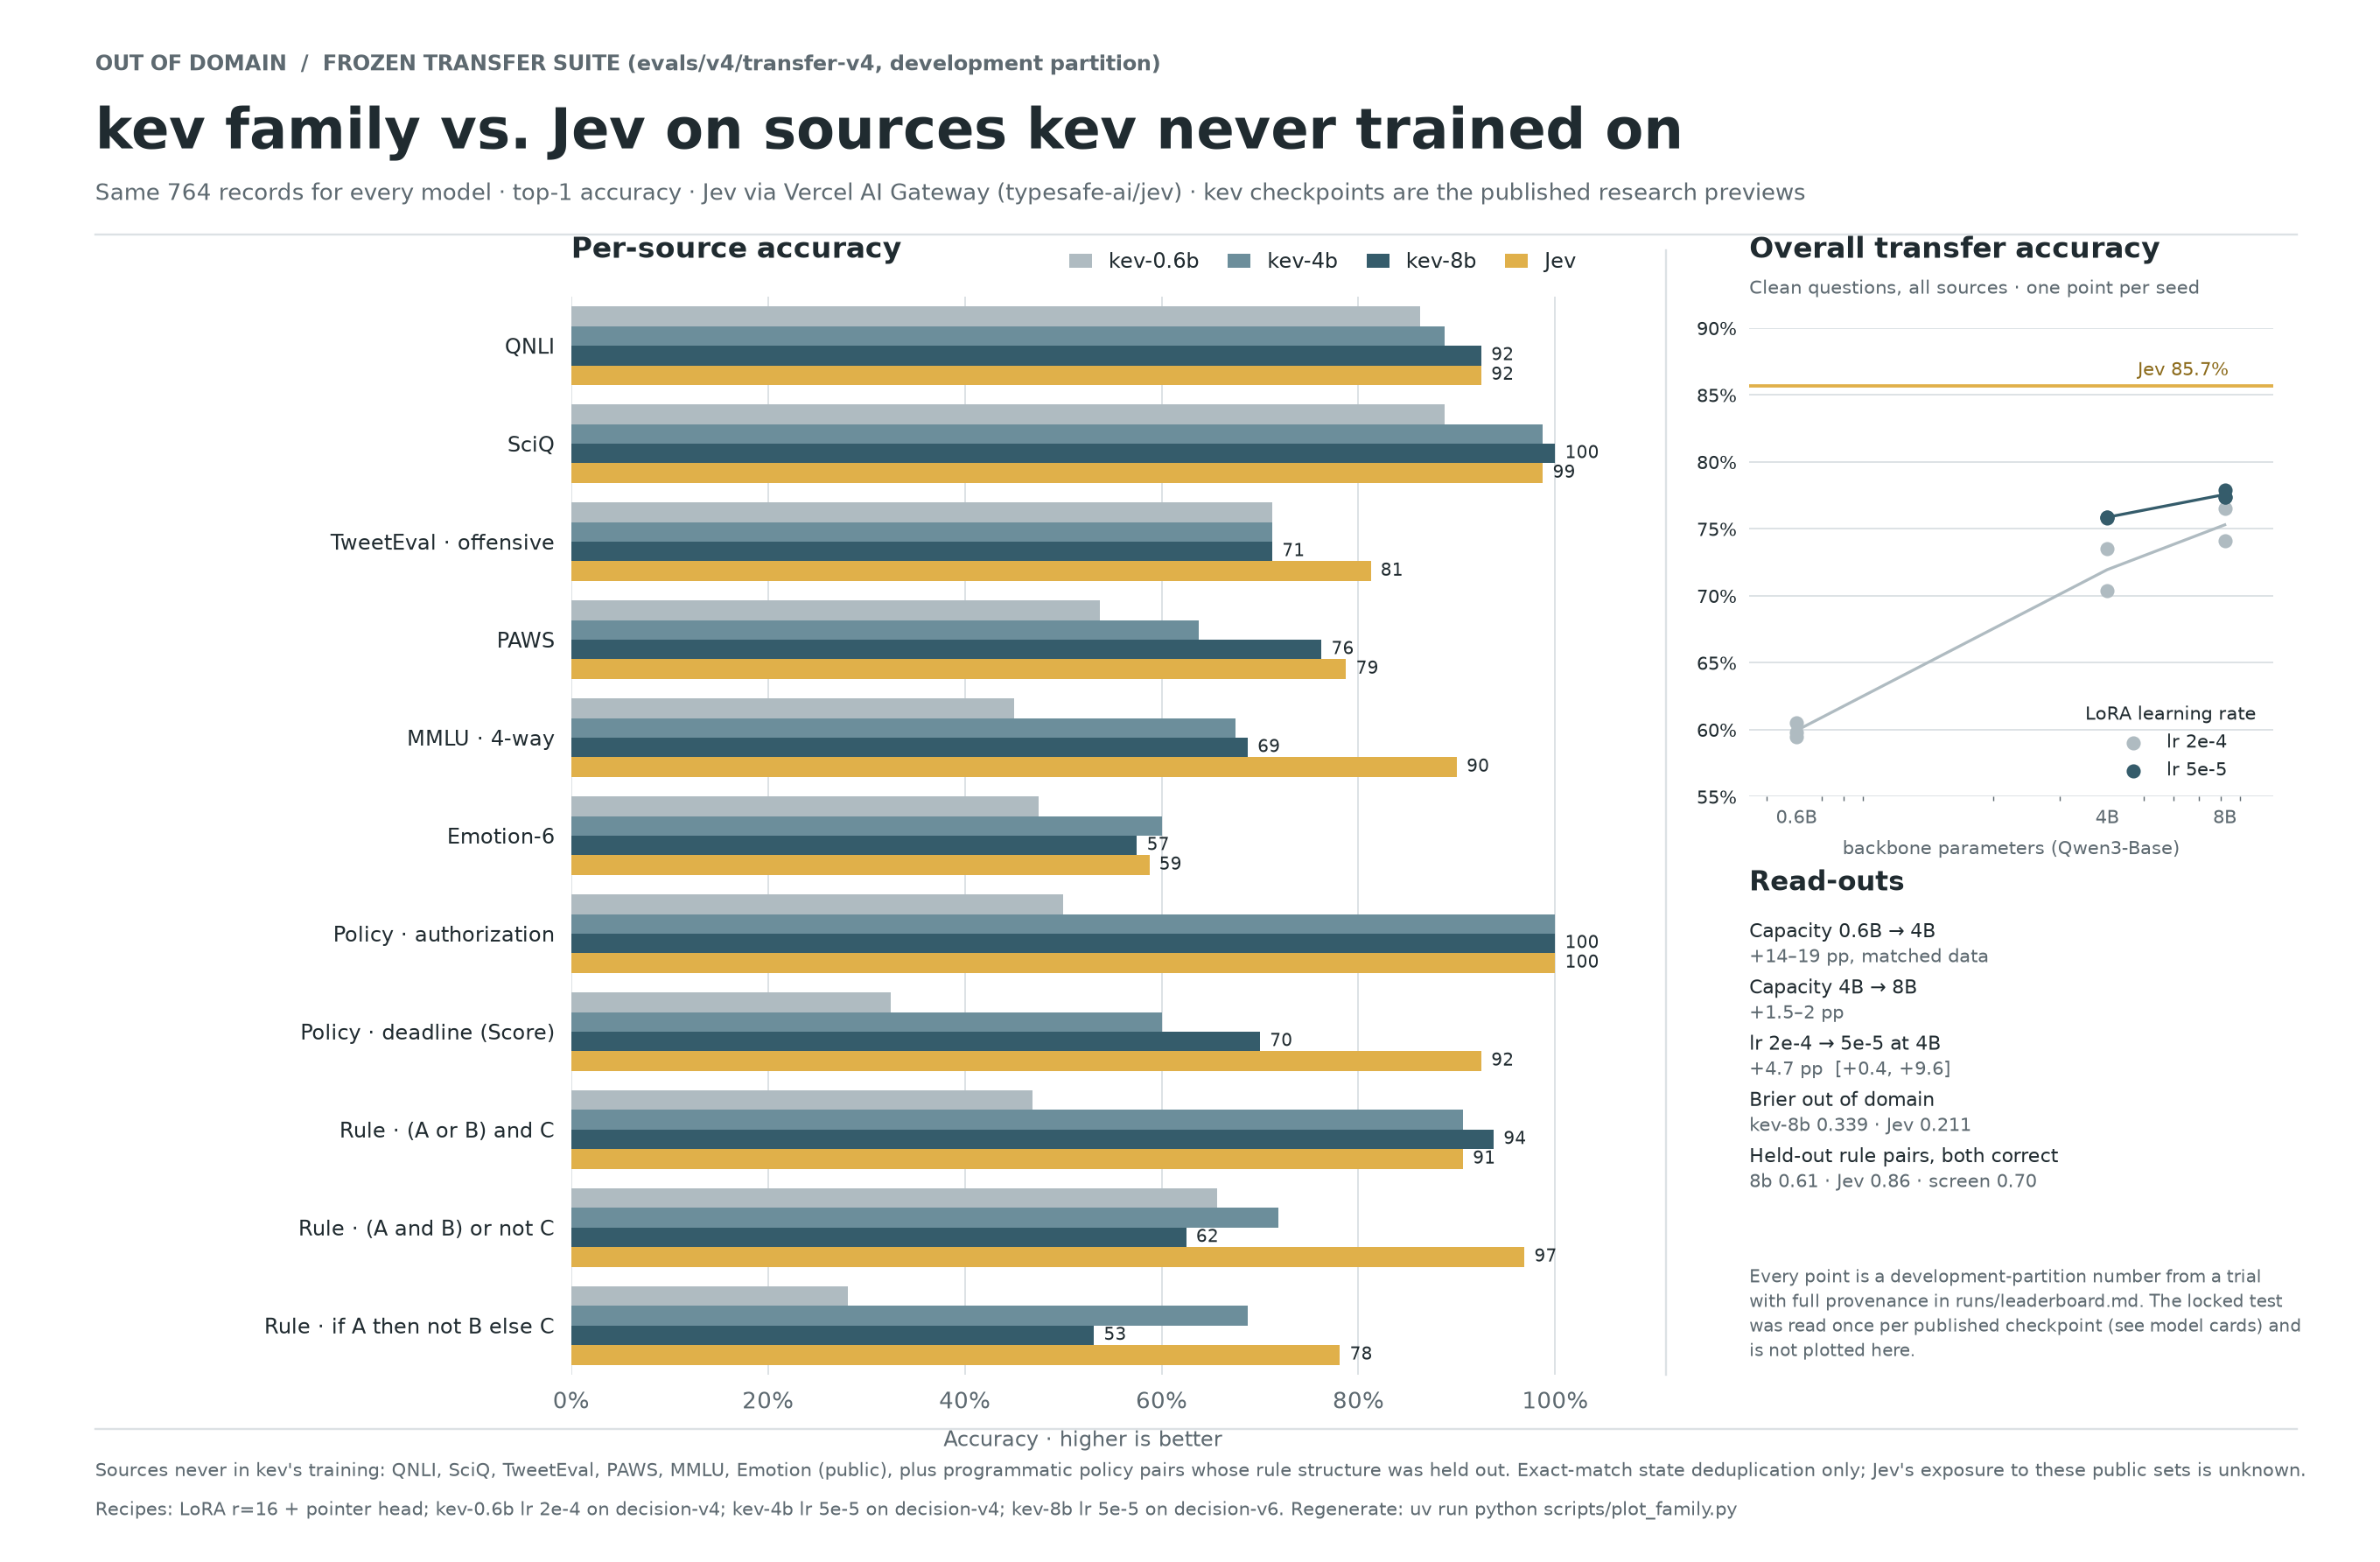
POST /v1/systemonewith TypeSafe's request and response shapes. Their SDK's quickstart runs unmodified. - A family, measured the same way. 0.5B, 0.6B, 4B and 8B checkpoints scored on frozen, checksummed suites with a locked test, against the real Jev on the same items. Out of domain: kev-4b 0.76, kev-8b 0.77, Jev 0.86.
- Runs on a laptop; trains in the cloud.
kev-0.5btrains in ~1h45m on an Apple M5; the 4B/8B recipes train in 40–70 min on one H100 via Modal and serve on a 32 GB Mac in bf16.
Installation
Requires Python 3.12+, uv, and Node 20+ for the playground. Serving is tested on Apple Silicon (MPS); training and evaluation on CUDA (H100 via Modal) and MPS.
git clone https://github.com/jaredpalmer/kev.git && cd kev
uv sync --extra serve
cd playground && npm install && cd ..
Download the weights
All checkpoints are on the Hugging Face Hub in the kev collection. --run accepts a Hub id; the base model downloads on first load. kev-4b is the one to start with: the best accuracy per byte, and it serves on a 32 GB Mac in bf16.