Gateway
LLM gateways and routers — a proxy between clients or agents and model providers for fallback, multi-provider access, cost control and token savings.
 decolua 30.8k · 7 days ago
Self-hosted gateway pointing any AI coding CLI (Claude Code, Codex, Cursor, Cline) at 40+ providers, with subscription→cheap→free auto-fallback and tool_result compression for 20-40% token savings.
 vllm-project 318 · today
Rust gateway that gives vLLM a stateful, OpenAI-compatible Responses API: server-side conversation state, server-side tool loops, SSE and WebSocket streaming, background runs — Codex-ready.

 router-for-me 55.3k · today
Turns your coding-CLI subscriptions (Claude Code, Codex, Antigravity, Kimi, Grok) into a local OpenAI/Gemini/Claude-compatible API — multi-account rotation in one Go proxy.
 Alishahryar1 60.6k · today
Provider-backed proxy that runs Claude Code, Codex or Pi on 25 cloud and local providers — fcc-* launchers, local Admin UI with validation, per-tier model routing, IDE/Discord/Telegram hookups.
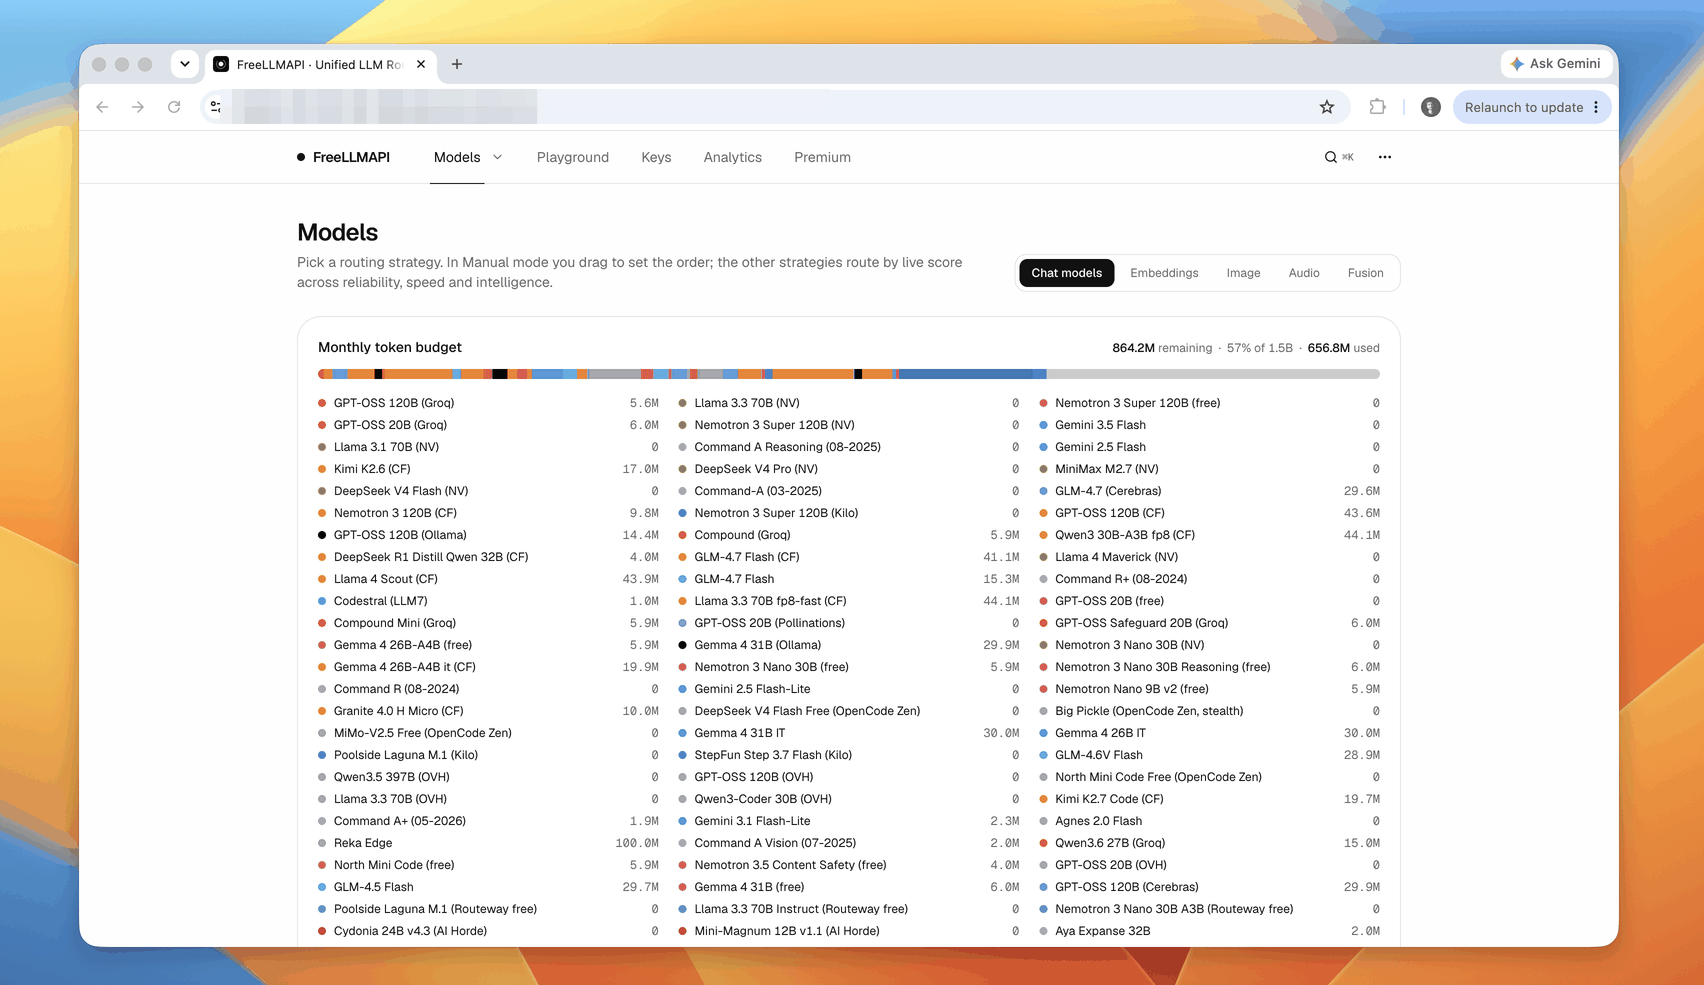
 tashfeenahmed 35.5k · today
OpenAI-compatible proxy that stacks free tiers of 18 LLM providers (~1.7B tokens/mo) behind one /v1 — smart routing, failover, per-key quota tracking; Claude Code and Codex shims included.

 HarnessRouter 3k · today
Self-hosted Apache-2.0 reference implementation of the Unified Harness Protocol: one OpenAI-Responses-style API running Codex, Claude Code, Hermes, Pi and DSH with sessions, streaming, files, traces.
 headroomlabs-ai 75.4k · today
Context compression layer for agents: squeezes tool outputs, logs, files and RAG chunks 20-95% before the LLM — reversible, local-first; library, proxy, one-command agent wrap, or MCP.

 BerriAI 61.3k · today
Open-source AI gateway: call 100+ LLM providers in OpenAI format via a Python SDK or self-hosted proxy — with cost tracking, virtual keys, guardrails, load balancing and logging.
 ulab-uiuc 3k · 6 days ago
UIUC's LLM routing library: 16+ trainable routers (KNN, MLP, matrix factorisation, Elo, graph, BERT) pick the best model per query, with xRouteBench and a train/serve CLI.
 githubnext 824 · 27 days ago
GitHub Next's local Jev bridge: a Bun/TypeScript POST /v1/systemone that translates typed decision questions into prompts for DiffusionGemma behind any OpenAI-compatible endpoint.

 Fast-Editor 629 · 2 days ago
Self-hosted LLM gateway wrapping Claude Code, Cursor or Codex with zero code changes — strips unused tools, compresses JSON tool results ~88%, semantic-caches, tier-routes easy work to local models.
 yetone 13.2k · today
Pick any model for any coding agent from one menu-bar app: a local gateway translating OpenAI, Anthropic and Gemini APIs, with subscription sign-ins and quota failover across accounts.
 IBM 4.6k · today
IBM's registry + proxy federating MCP, A2A and REST/gRPC into one governed endpoint: discovery, auth, rate limits, guardrails, OTel tracing, 40+ plugins — scales to K8s with Redis federation.
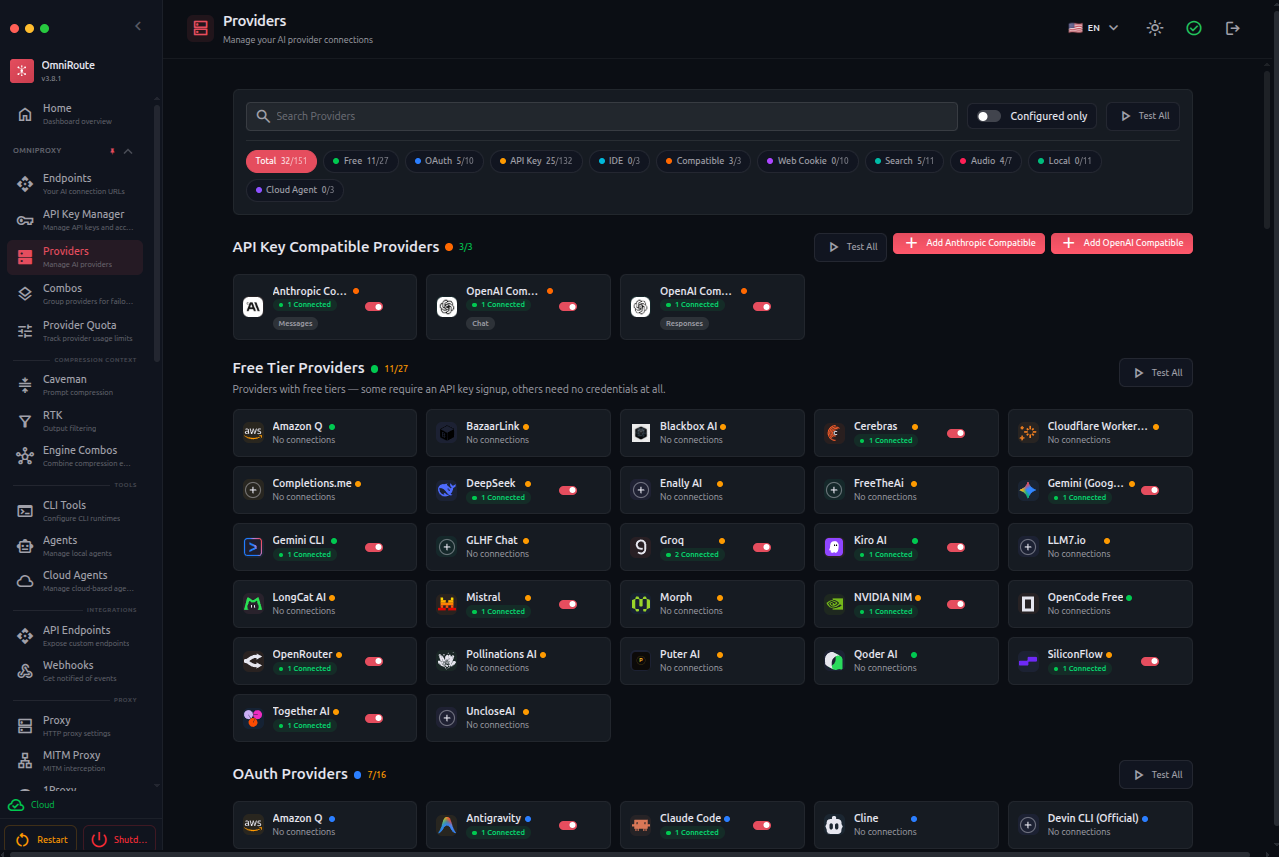
 diegosouzapw 76.8k · today
Free MIT AI gateway for coding CLIs: one endpoint over 352 providers (150+ free tiers) and 1,200+ models with quota-aware auto-fallback, RTK+Caveman token compression, MCP/A2A and a desktop app.
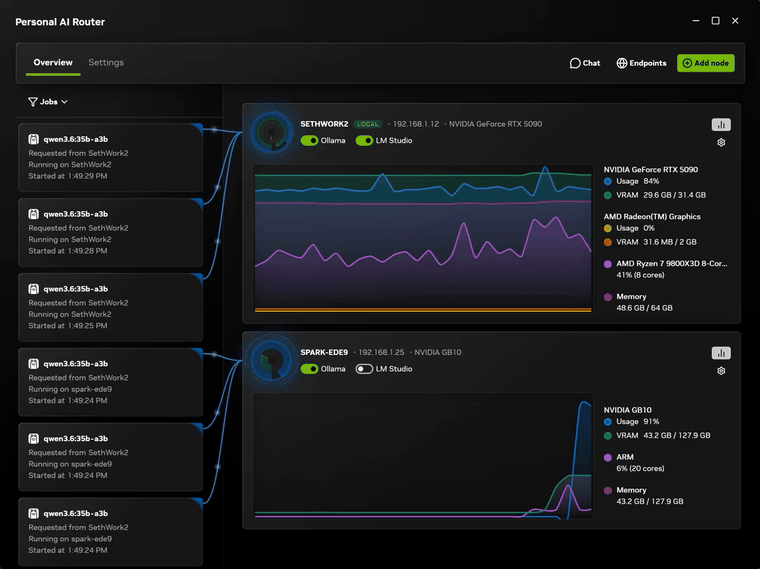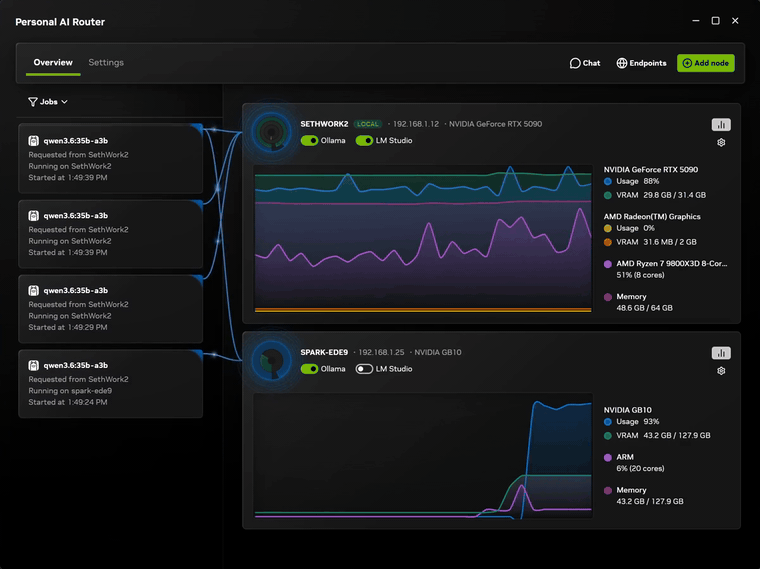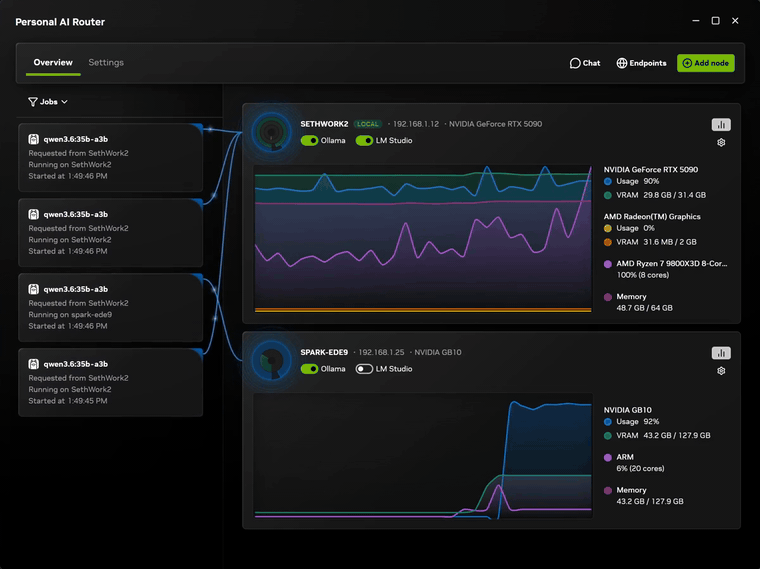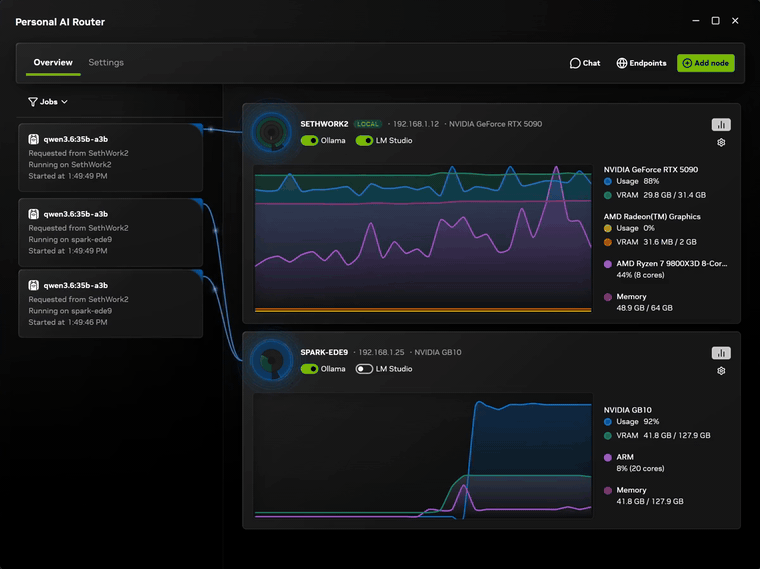
 NVIDIA 1.6k · yesterday
NVIDIA's local inference router: pairs home machines running Ollama or LM Studio behind OpenAI-, Anthropic- and Ollama-compatible endpoints, sending each request to the best available node.

 katanemo 7.1k · 8 days ago
AI-native Envoy-based proxy for agentic apps: agent orchestration via a 4B routing model, smart LLM routing, guardrail filter chains and zero-code OTEL traces. Rust, framework-agnostic.
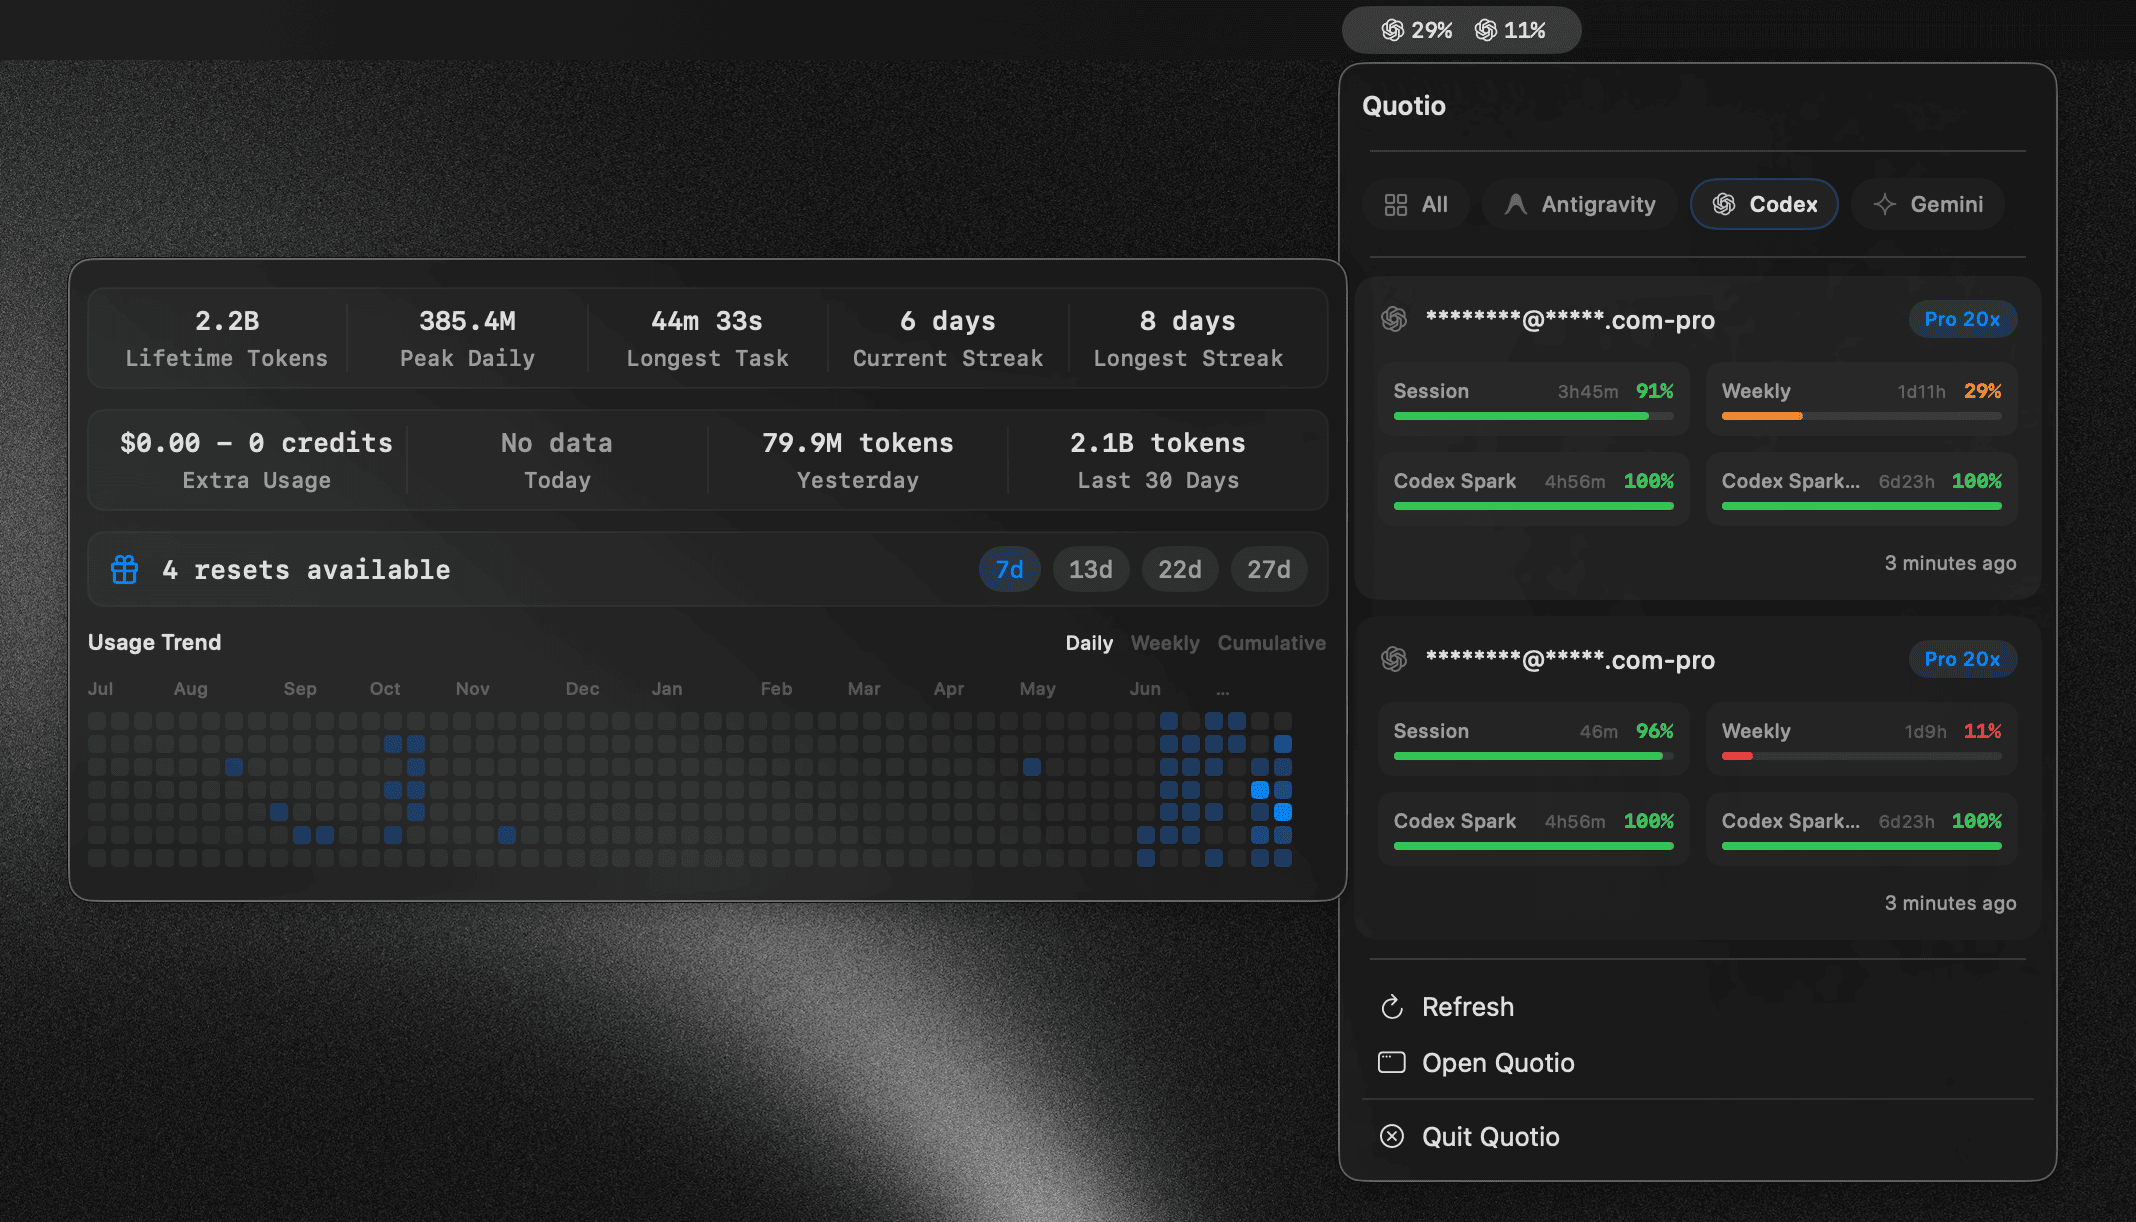
 nguyenphutrong 4.9k · yesterday
Native macOS menu-bar front-end for CLIProxyAPI: pool your Claude, Codex, Qwen and Copilot accounts behind one local proxy with live quota bars, auto-failover and one-click CLI wiring.
 weave-os 5.6k · today
Weave's Go model router: drop-in proxy speaking Anthropic, OpenAI and Gemini APIs that scores each request with an on-box ONNX embedder (Avengers-Pro clusters) and routes to the cheapest fit model.
 google 1.1k · today
Zero-trust P2P mesh for agents, published by Google: libp2p nodes with portable crypto identities self-discover, and an MCP sidecar lets an agent invoke tools on any node — cloud, local or edge.
 vllm-project 6.2k · today
vLLM's programmable decision layer: one endpoint for your agent harness that selects or combines models per call by policy — quality, latency, cost, location — across local and cloud backends.